
Contact Us
Retrieval-augmented generation, or RAG, is an AI architecture that searches your own documents before the language model answers. The model reads what it retrieved and generates a response grounded in those sources, with citations. This is what stops an AI from inventing your company's policies. Before you spend a dollar, you deserve to know exactly what you are buying and why it matters.
LLM is the engine behind tools like ChatGPT, Claude, and Gemini. It understands language, generates text, and reasons through problems. But here is the catch — it only knows what it learned during training. It does not know your company's pricing, your return policy, your latest product spec, or what your compliance team decided last Tuesday. Ask it a company-specific question and it will invent an answer that sounds plausible. That invention is called hallucination, and it is the number one reason AI development projects stall or get shut down.
(RAG) solves this by adding a search layer before the model speaks. When a user asks a question, the RAG system searches your documents, knowledge base, or database first, retrieves the relevant information, and hands it to the LLM as context. The model then generates an answer grounded in your actual data — with source citations your team can verify. No more guessing. No more hallucinating your company's policies.
Custom LLM development goes one step further. Instead of using a general-purpose model off the shelf, we fine-tune or train a model specifically for your domain. A healthcare LLM that understands clinical terminology and respects HIPAA compliance. A legal LLM that reads contracts the way a junior associate would — but in seconds. A finance LLM that interprets regulatory filings without you explaining what a 10-K is.
Every company that has tried plugging a general-purpose LLM into their operations has hit the same wall. The model writes beautifully. It responds fast. And then someone on the team asks about your warranty terms, and the model invents a policy that has never existed. A customer asks about a product spec, and the model confidently quotes a feature your product does not have. A compliance officer asks about a regulation, and the model cites a document that does not exist.
This is not a bug. It is a feature of how these models work. They were trained on the open internet — not on your SOPs, your product catalog, or your regulatory filings. The companies that get stuck here usually try one of three things. All three are wrong.
They write longer and longer system prompts, hoping the model stops making things up. It helps at the margins. It does not solve the core problem — the model still has no access to your data.
They retrain the model on company documents. The model gets better at sounding like your brand, but it still has no live connection to your current information. Fine-tuning bakes knowledge into the model's weights. The moment your documents change, the model is out of date.
They conclude that AI is not ready for their business. That is also wrong. The technology works. The architecture just needs to be right.
The right answer is a retrieval layer that connects the model to your live data, combined with guardrails that stop the model from answering when it does not have verified information. That is what a production RAG system does. That is what our RAG development services deliver. And that is the difference between AI that impresses in a demo and AI that runs in your operations.
Here is a project that shows what production RAG actually looks like inside a business.
A US-based healthcare services company had a 12-person support team fielding 300+ calls and tickets daily. Agents spent an average of 14 minutes per ticket — not because the questions were hard, but because finding the right answer required searching across a 4,000-page knowledge base spread across Confluence, SharePoint, and three different PDF policy manuals. Answers were inconsistent across agents. New hires took four months to ramp.
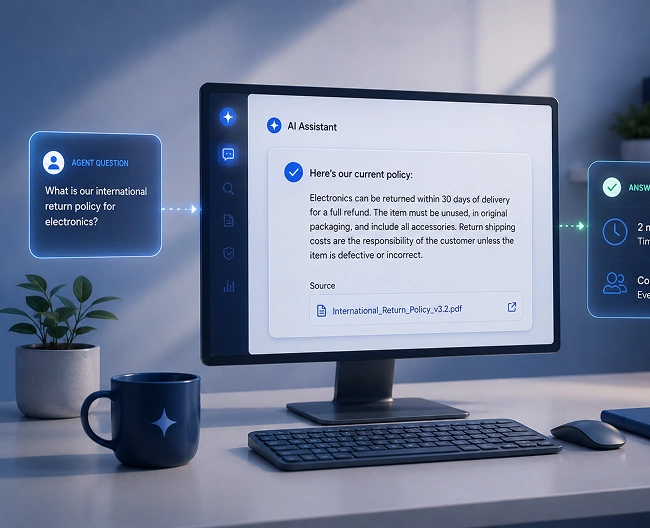
A RAG-powered knowledge assistant embedded directly into their helpdesk platform. We ingested all 4,000 pages, processed them into optimized chunks, generated embeddings, stored them in a vector database, and connected the retrieval pipeline to a fine-tuned LLM. When an agent receives a question, they type it into the assistant and get an accurate, source-cited answer in under two seconds.
Average resolution time dropped from 14 minutes to 3.5 minutes.
Answer accuracy, verified by supervisor audit
New hire ramp, down from four months
Annual staffing savings — 3 fewer FTEs
We do not hand you a model and call it a day. Building a production RAG system means getting a dozen interconnected decisions right. We handle all of them.
This is the core of what most companies need. We build the retrieval pipeline that connects your AI to your data — documents, knowledge bases, databases, wikis, support tickets, product catalogs, policy manuals. We handle document ingestion, chunking strategies, embedding generation, vector storage, retrieval logic, re-ranking, and prompt engineering that turns raw data into accurate, source-cited answers.
Every RAG system we build includes metadata filtering, relevance scoring, and source attribution so your team can verify every single response the AI gives.
When your use case demands domain-specific understanding that retrieval alone cannot deliver, we fine-tune or build custom language models. We curate training datasets from your business data, select the right base model, manage the fine-tuning process, evaluate performance against your benchmarks, and deploy the result to your infrastructure.
Fine-tuning is not always the answer. We will tell you when RAG alone is enough — and save you the money — before you commit to a more expensive build. For a deeper look at LLM application development, we have written a comprehensive guide.
Your RAG system is only as good as the data behind it. We build the ingestion pipelines that pull content from your sources — PDFs, Word docs, Confluence pages, Notion databases, Salesforce records, SharePoint libraries, Slack archives — process everything into searchable chunks, generate embeddings, and keep the system synchronized as your data changes.
We handle the messy work most vendors skip: deduplication, version control, access permissions, and automatic re-indexing when source documents update. This is where the API development layer matters — we build connectors that pull from your systems securely and reliably.
Not every project needs a custom model or a retrieval pipeline. Sometimes you need an application built on top of an existing LLM — a summarization tool, a document drafting assistant, a contract analyzer, a customer-facing Q&A interface. We build custom software powered by LLMs, scoped to do one thing well, and deployed to run inside your existing workflows.
Your AI system needs to work inside the tools your team already uses. We integrate LLM and RAG solutions with CRMs, ERPs, helpdesks, internal portals, communication platforms, and third-party APIs. The system fits your stack — it does not create a parallel universe your IT team has to maintain on the side.
Every system we deploy includes evaluation frameworks that measure retrieval accuracy, answer relevance, latency, and hallucination rates. We set up guardrails — confidence thresholds, fallback responses, source validation, and human escalation triggers. Post-launch, we monitor performance, retune retrieval logic, and adapt the system to new data sources as your business grows.
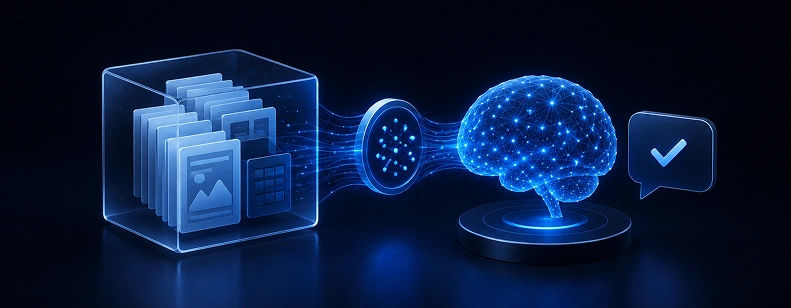
RAG System Design and Development
This is the core of what most companies need. We build the retrieval pipeline that connects your AI to your data — documents, knowledge bases, databases, wikis, support tickets, product catalogs, policy manuals. We handle document ingestion, chunking strategies, embedding generation, vector storage, retrieval logic, re-ranking, and prompt engineering that turns raw data into accurate, source-cited answers.
Every RAG system we build includes metadata filtering, relevance scoring, and source attribution so your team can verify every single response the AI gives.
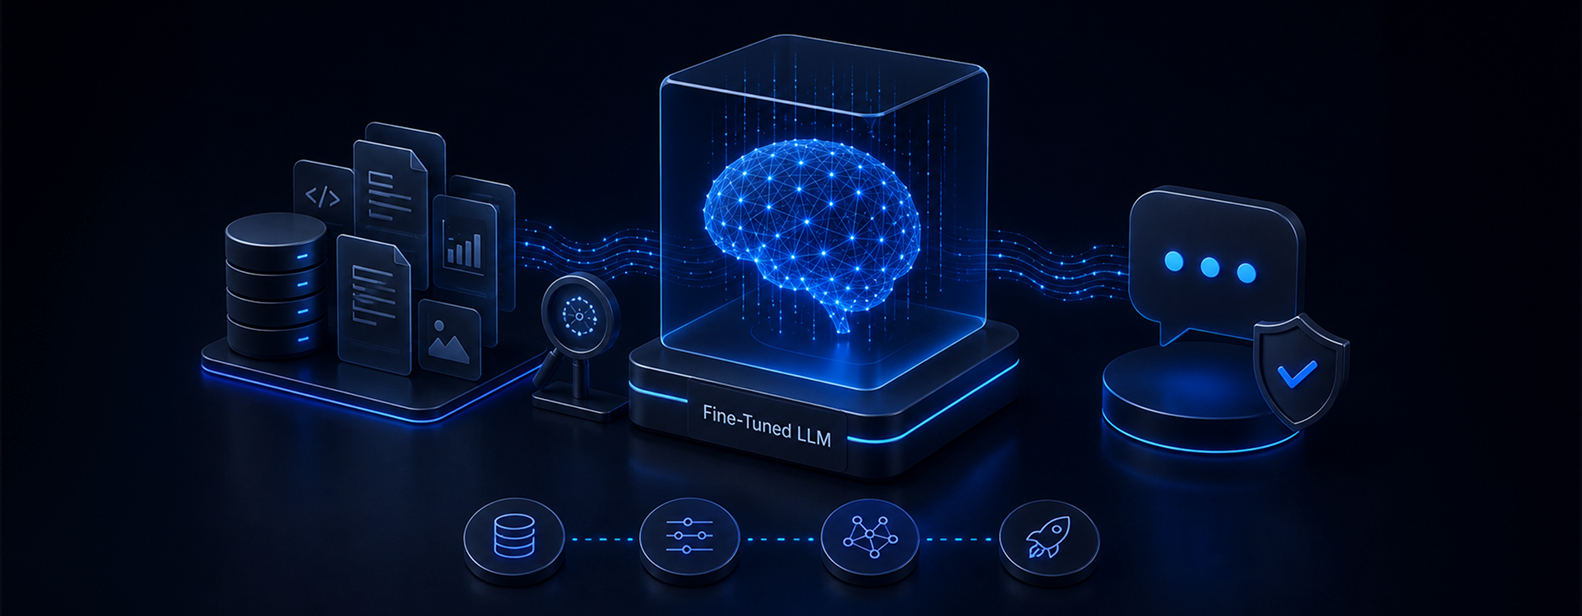
Custom LLM Development and Fine-Tuning
When your use case demands domain-specific understanding that retrieval alone cannot deliver, we fine-tune or build custom language models. We curate training datasets from your business data, select the right base model, manage the fine-tuning process, evaluate performance against your benchmarks, and deploy the result to your infrastructure.
Fine-tuning is not always the answer. We will tell you when RAG alone is enough — and save you the money — before you commit to a more expensive build. For a deeper look at LLM application development, we have written a comprehensive guide.
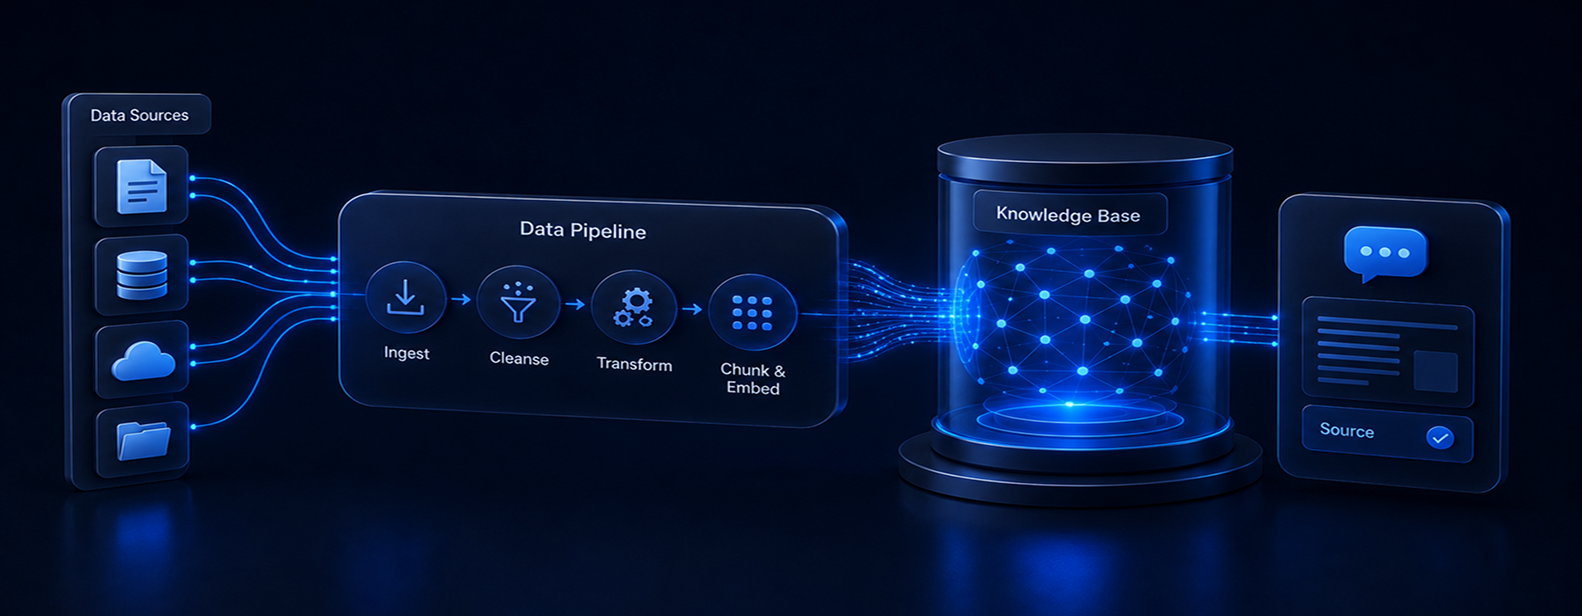
Knowledge Base and Data Pipeline Engineering
Your RAG system is only as good as the data behind it. We build the ingestion pipelines that pull content from your sources — PDFs, Word docs, Confluence pages, Notion databases, Salesforce records, SharePoint libraries, Slack archives — process everything into searchable chunks, generate embeddings, and keep the system synchronized as your data changes.
We handle the messy work most vendors skip: deduplication, version control, access permissions, and automatic re-indexing when source documents update. This is where the API development layer matters — we build connectors that pull from your systems securely and reliably.
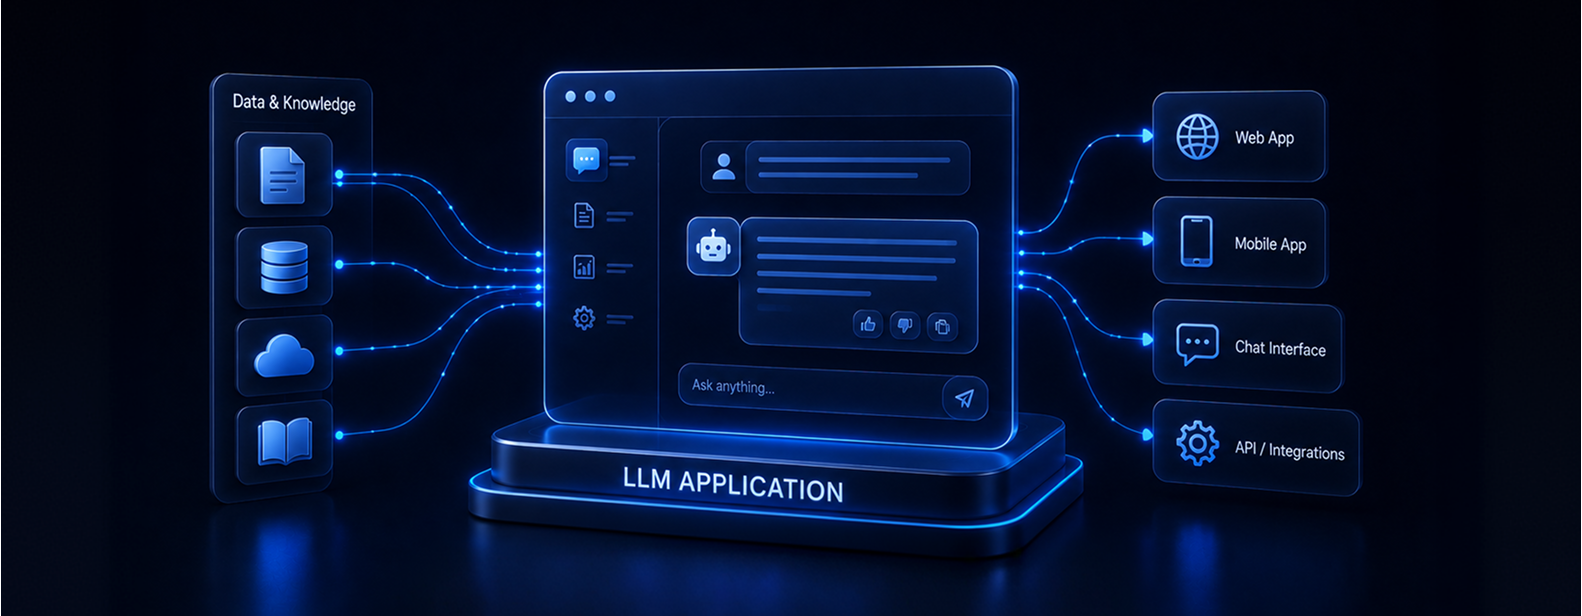
LLM Application Development
Not every project needs a custom model or a retrieval pipeline. Sometimes you need an application built on top of an existing LLM — a summarization tool, a document drafting assistant, a contract analyzer, a customer-facing Q&A interface. We build custom software powered by LLMs, scoped to do one thing well, and deployed to run inside your existing workflows.
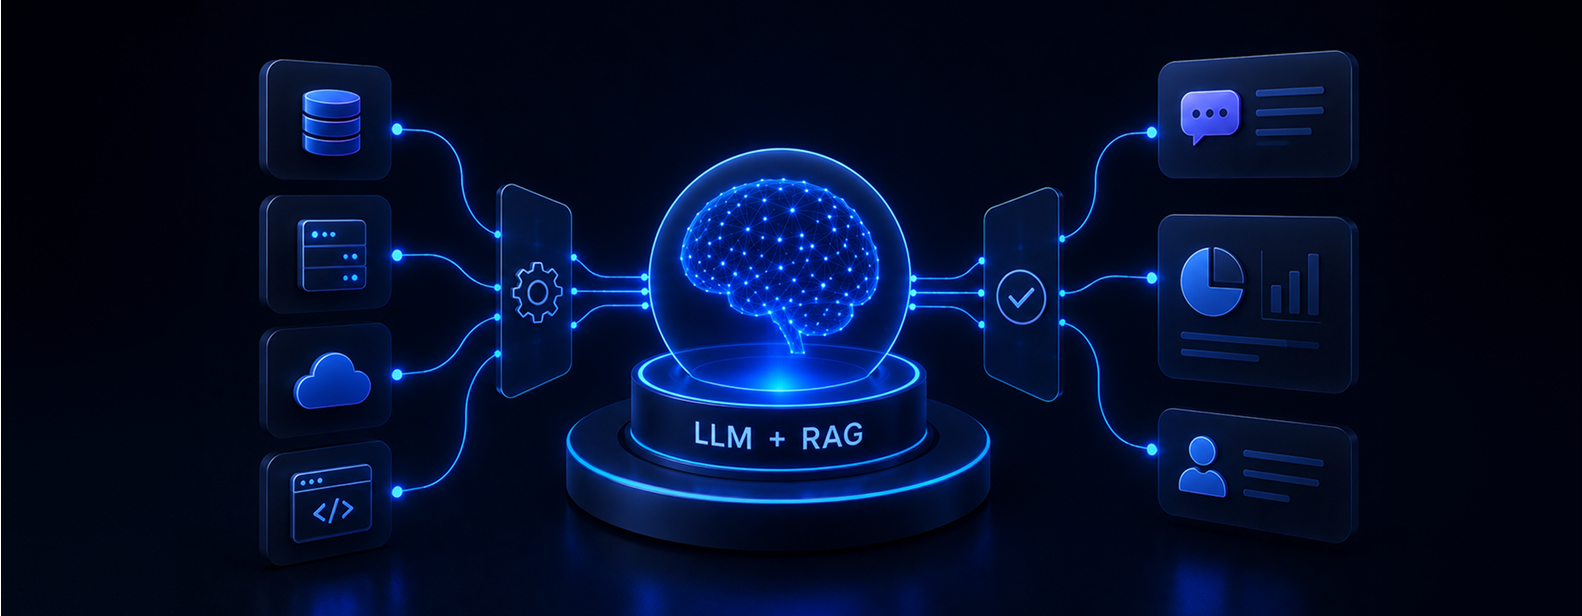
LLM and RAG Integration with Existing Systems
Your AI system needs to work inside the tools your team already uses. We integrate LLM and RAG solutions with CRMs, ERPs, helpdesks, internal portals, communication platforms, and third-party APIs. The system fits your stack — it does not create a parallel universe your IT team has to maintain on the side.
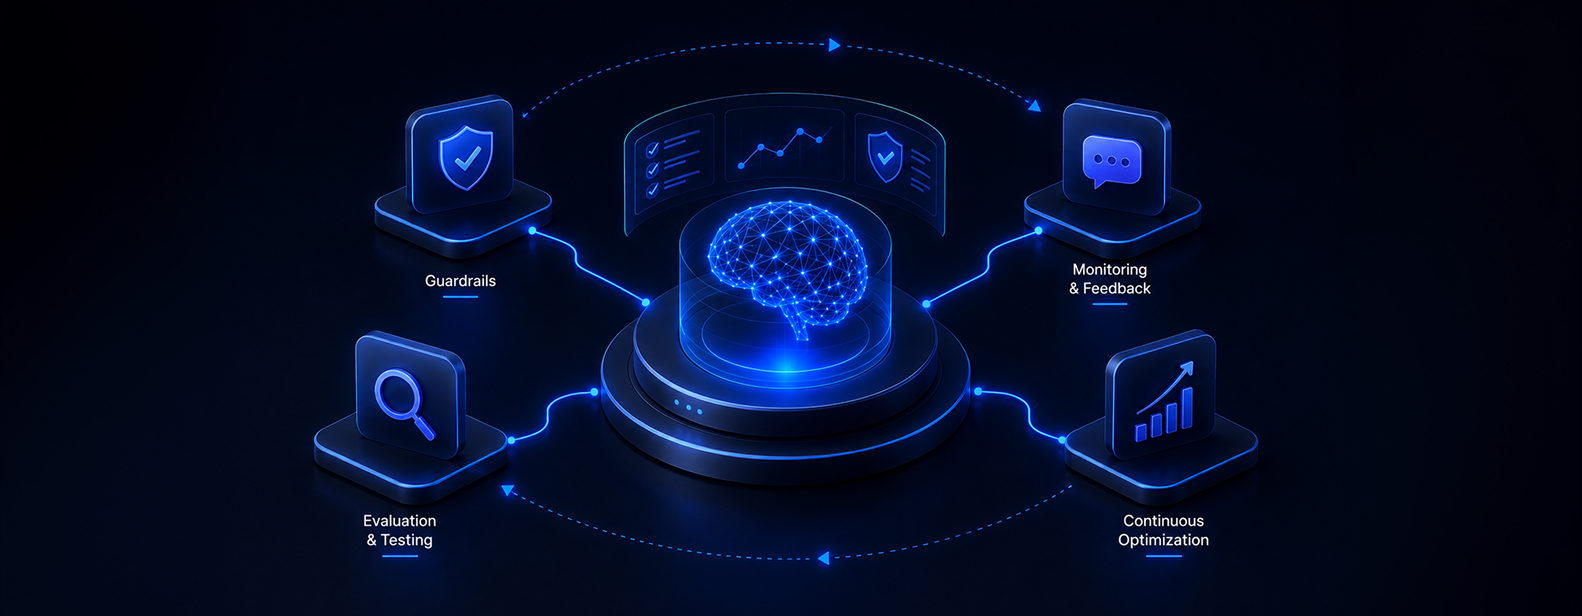
Evaluation, Guardrails, and Ongoing Optimization
Every system we deploy includes evaluation frameworks that measure retrieval accuracy, answer relevance, latency, and hallucination rates. We set up guardrails — confidence thresholds, fallback responses, source validation, and human escalation triggers. Post-launch, we monitor performance, retune retrieval logic, and adapt the system to new data sources as your business grows.
Most vendors answer this question with "whichever one we sell." Here is the actual breakdown so you can make the right call before you spend anything.
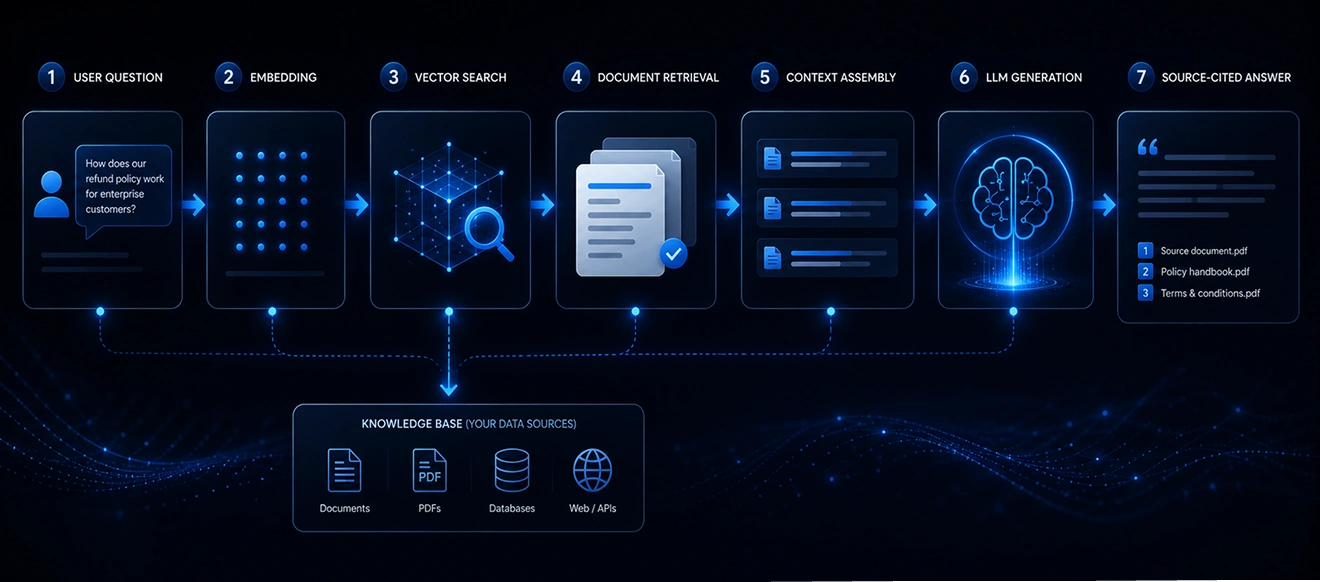
When someone asks your AI a question, here is exactly what happens inside a well-built RAG system:
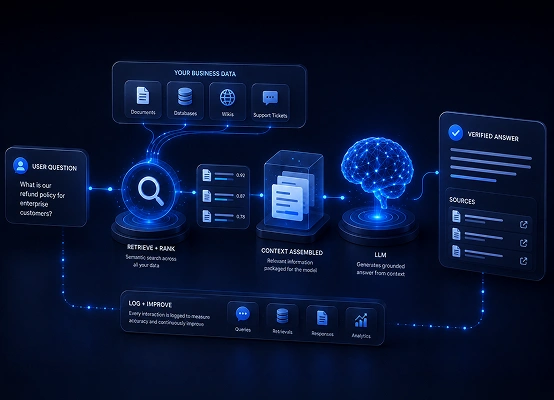
A user types a question into your support portal, internal tool, Slack bot, or chat interface.
Before the LLM sees the question, the retrieval pipeline converts it into a vector — a mathematical fingerprint of meaning — and searches your indexed documents for the closest matches. This is not keyword search. It understands what the question means, even if the words do not match exactly.
The system pulls back the most relevant chunks of information from your knowledge base, re-ranks them by relevance, and filters by metadata (date, department, document type, access level).
The retrieved documents are packaged together with the original question and system instructions. This assembled context is what gets sent to the language model.
The LLM reads the context and generates a response based on the documents it was given. It is not pulling from its training data. It is reading your files and answering from them — the way a prepared employee would after reviewing the relevant materials.
Every answer includes links to the source documents it used. Your users can click through and verify. No trust required. Full transparency.
Every query, every retrieval, every response. We use this data to measure accuracy, catch edge cases, and make the system sharper over time.
Take a process your team runs a hundred times a day — answering a customer question that has a documented answer somewhere.
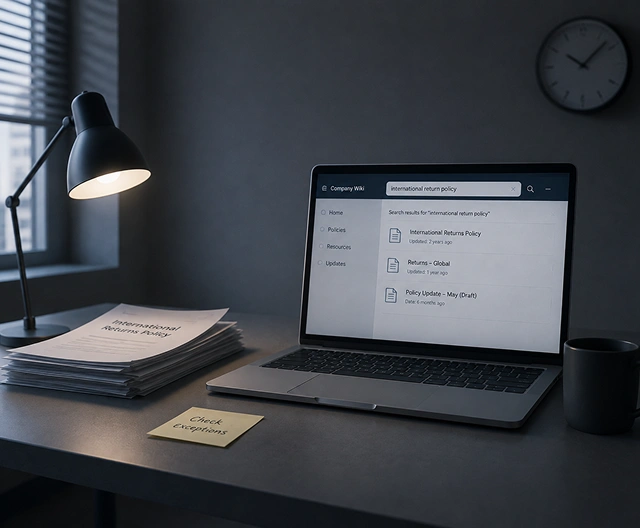
A customer asks whether their plan covers a specific procedure. The agent opens Confluence, searches three different phrasings, gets forty results, opens the wrong policy PDF, switches to SharePoint, and finally pings a senior colleague on Slack. Fourteen minutes later they answer. The next agent, asked the same question an hour later, gives a slightly different answer from a different document. New hires need four months before they can respond without checking with someone.
The agent types the question into the assistant embedded in their helpdesk. In under two seconds it returns an answer with links to the exact policy sections it drew from. The agent skims the sources, confirms, and replies. Three and a half minutes. The same answer every time, from every agent, on every shift — because every answer comes from the same governed set of documents. New hires are productive in six weeks.
We would rather lose a deal over honesty than win one on false expectations. Here is the truth.
(and anyone who says otherwise is selling you something):
The cost of AI and ML development varies widely depending on scope. But for RAG specifically, the math usually works in the first quarter — especially for teams with high query volumes and expensive human time.
Two hundred production applications shipped. Our RAG systems run under real load with real users asking real questions that do not match the test set.
GPT, Claude, Gemini, Mistral, LLaMA, Cohere, open-weight models. We pick the one that fits your use case, your budget, and your compliance requirements. We do not push the model we have a partnership with.
Encryption, access controls, data residency, audit logging. If you need HIPAA-compliant AI, we design for it before the first line of code, not as a last-minute patch.
Our US office works in your time zones. We have delivered generative AI solutions for American startups and enterprises for years. You are not onboarding engineers who need to learn your regulatory environment on your budget.
Code, models, pipelines, vector databases, infrastructure. Full ownership, zero lock-in. When the project ends, your system is entirely yours.
If your use case is better served by a simpler LLM application, a rule-based system, or even a well-structured search page — we will say so. We would rather build trust than build something unnecessary.
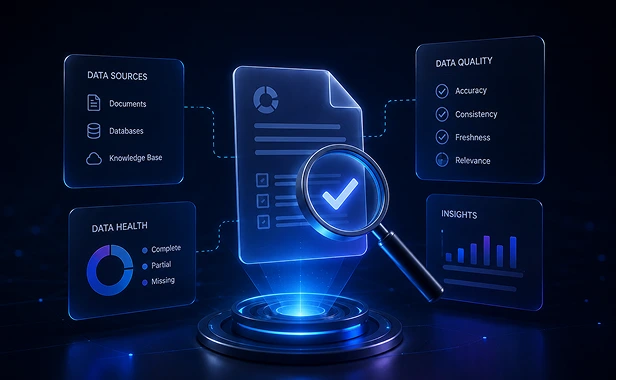
We map the use case, interview your stakeholders, and audit every data source. What documents exist? What format? How often do they change? Where are the gaps and contradictions? We define success metrics and cut scope that does not earn its place. If the data is not ready, we say so — and help you fix it before building on a weak foundation.
Output: Use case brief, data readiness assessment, go/no-go recommendation with estimated ROI.
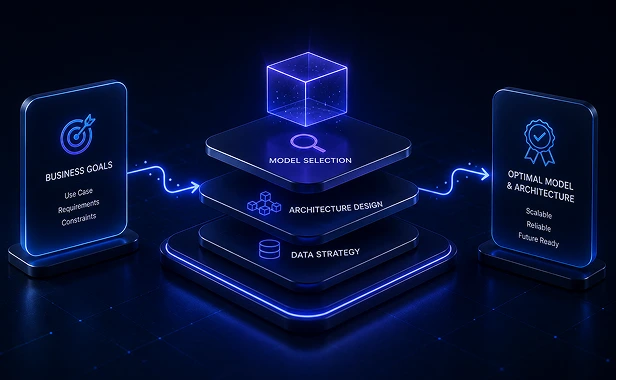
We design the full system — retrieval pipeline, embedding strategy, vector database, LLM selection, chunking approach, prompt architecture, re-ranking logic, and integration points. Every technical decision traces to your use case and constraints, not our preferences.
Output: Architecture document, data flow diagrams, model selection rationale.
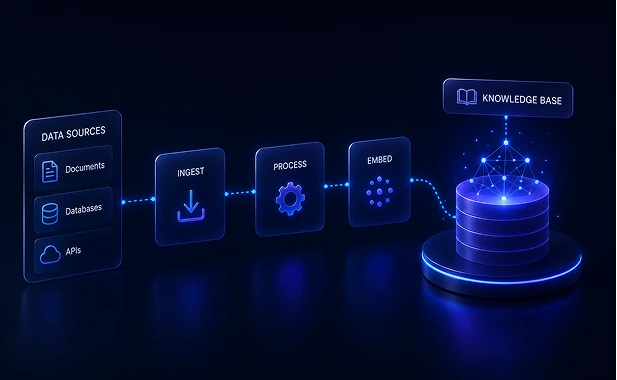
We ingest your documents, process them into optimized chunks, generate embeddings, and load everything into the vector database. We build synchronization pipelines so the knowledge base stays current as your sources change. Deduplication, versioning, access controls, and automatic re-indexing are all part of this stage.
Output: Live, searchable knowledge base with automated ingestion and sync pipeline.
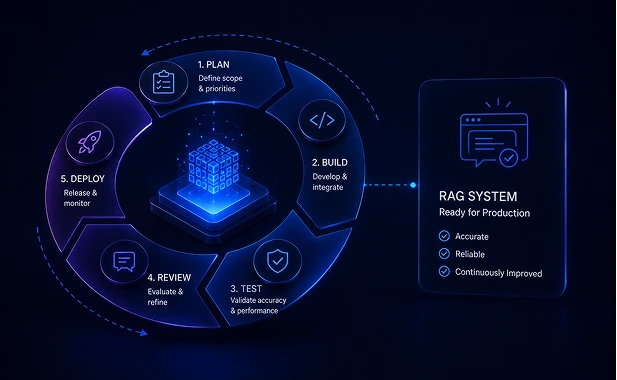
Short build cycles with working demos at the end of every sprint. You test the system with real queries from your actual team. Your feedback shapes retrieval logic, prompt engineering, and response formatting as the system matures. No black box. No surprise at the finish line.
Output: Functional RAG system with documented iteration history.
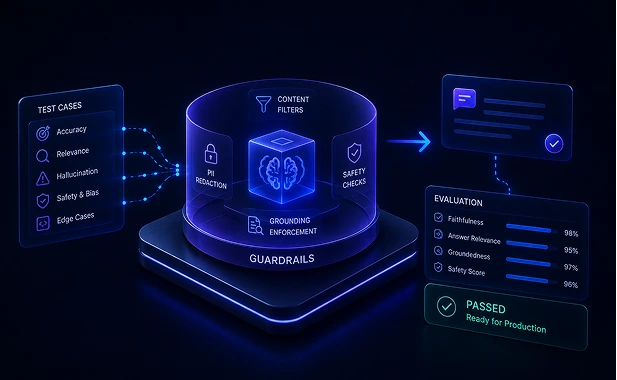
We test against real-world queries, edge cases, adversarial inputs, and retrieval failures. We measure retrieval accuracy, answer relevance, latency, hallucination rate, and cost per query. We add guardrails — confidence thresholds, source validation, fallback responses, human escalation triggers, and stop controls.
Output: Evaluation reports, guardrail configurations, accuracy benchmarks.
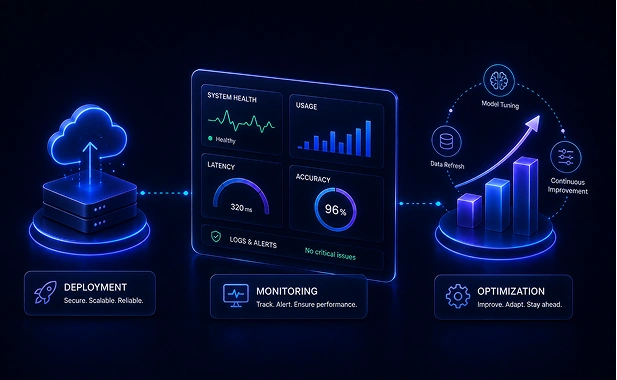
We deploy to your cloud — AWS, Google Cloud, or Azure. We connect to your systems, configure monitoring dashboards, and run load tests. Post-launch, we retune retrieval logic, update embeddings as data changes, refine prompts, and adapt to new use cases. Your system gets sharper every month.
Output: Production deployment with monitoring, monthly performance reports, and continuous optimization.
The retrieval strategy that works for a real estate brokerage will fail in a hospital. Different data, different regulations, different stakes. We build systems that respect the specifics.
RAG systems that retrieve from clinical guidelines, drug databases, patient records, and policy documents — with HIPAA-compliant architecture designed from the ground up. Use cases include clinical decision support, patient FAQ assistants, prior authorization research, and medical record summarization. We work closely with our healthcare software development team to ensure every build meets the compliance bar.
LLM applications that answer property questions, pull listing data, summarize lease agreements, and give agents instant access to market reports. RAG pipelines connected to MLS feeds, document libraries, and CRM records. If you are building a real estate platform, adding a RAG-powered assistant can cut agent research time by 60% or more.
AI tutoring systems grounded in course materials, textbooks, and institutional knowledge bases. Students ask questions and get answers sourced from their actual curriculum — not the open internet. Educators get grading assistance and content generation tools built on their standards. We have built education platforms that serve thousands of learners — adding RAG makes them dramatically smarter.
RAG-powered booking assistants and customer service tools that retrieve from itinerary databases, fare rules, cancellation policies, and destination guides. Travelers get accurate, real-time answers instead of generic responses that miss the details. Our travel software development team builds the platforms these agents live inside.
Knowledge assistants connected to exercise libraries, nutrition databases, and membership records. Members get personalized guidance grounded in your actual programs and protocols. Staff get instant access to operational policy documents. Pair this with our fitness software development for a fully integrated experience.
We are not locked into one vendor or one cloud. We choose the right tools for your use case, your data, and your compliance requirements.

GPT

Claude

Gemini
Mistral

Cohere Command

Pinecone

Weaviate

ChromaDB

PostgreSQL

Redis

Elasticsearch

Qdrant

Langchain

Semantic Kernel

Haystack

LlamaIndex

AWS

Google Cloud

Microsoft Azure

Docker

Kubernetes

Unstructured.io

Apache Tika

Confluence

Notion

SharePoint

Salesforce Connectors

LangSmith

Weights & Biases
Most vendors hide pricing behind a "contact us" wall. We think that wastes your time. Here are real ranges from projects we have delivered. Most of our RAG clients invest between $40,000 and $100,000 and see payback within the first two quarters. For a detailed breakdown, read our RAG implementation cost guide.
RAG stands for retrieval-augmented generation. It is a technique where an AI system searches your business data before generating an answer. Instead of relying on what the model learned during training, RAG grounds every response in your actual documents, databases, and knowledge bases. This dramatically reduces hallucination and gives you answers you can trace back to a source.
RAG connects a language model to your live data at the time of each query — the model reads relevant information before answering. Fine-tuning retrains the model itself on your data so it learns your domain’s language, patterns, and reasoning. RAG keeps answers current and verifiable. Fine-tuning gives the model deeper domain understanding. Production systems often use both together.
Custom LLM development involves training or fine-tuning a large language model on your specific business data so it understands your industry’s terminology, tone, and reasoning patterns. Instead of a general-purpose model, you get one that thinks the way your domain experts do. Our LLM development guide covers this in depth.
PDFs, Word documents, web pages, knowledge base articles, wiki entries, support tickets, CRM records, database tables, Slack messages, email archives, product catalogs, policy manuals, clinical guidelines, legal contracts — essentially any text-based data source your business generates or maintains.
Well-architected RAG systems achieve 85 to 95 percent retrieval accuracy with proper chunking strategies, quality embeddings, and relevance tuning. Accuracy depends on data quality, document structure, and how carefully the retrieval pipeline is configured for your specific use cases.
A single-use-case RAG system can go live in three to five weeks. A production system with multiple data sources and integrations takes two to four months. Enterprise systems with custom LLM fine-tuning and compliance requirements run four to eight months. We have written about how long AI development takes in more detail.
Projects range from $15,000 for a starter system to $300,000+ for an enterprise LLM + RAG platform. Most clients invest between $40,000 and $100,000 for production-grade RAG with guardrails, integrations, and ongoing optimization. See our full RAG cost breakdown for more detail.
Yes. We integrate RAG systems with CRMs, ERPs, helpdesks, content management systems, Slack, Teams, internal portals, and third-party APIs through secure API integrations. The system fits your stack — it does not replace it.
Multiple layers: retrieval grounding (the model only answers from retrieved documents), confidence thresholds (uncertain answers get flagged or blocked), source citation (every response links to its source), output validation, and human-in-the-loop escalation for high-stakes queries. RAG reduces hallucination by 80 to 95 percent compared to raw LLM outputs. Guardrails cover the remaining gap.
Yes. You own the code, the models, the vector database, the data pipelines, and the infrastructure. No vendor lock-in. No recurring platform fees you did not agree to.
A vector database stores your documents as mathematical representations called embeddings that capture meaning, not just keywords. When a user asks a question, the system converts it into the same format and finds the most semantically similar documents — even if the exact words differ. This is how RAG achieves dramatically better results than traditional keyword search.
We build automated ingestion pipelines that monitor your data sources for changes. When a document is updated, added, or removed, the system re-processes it, generates new embeddings, and updates the vector database automatically. Your AI always answers from the latest version of your data — not a stale snapshot from three months ago.


